Why a comparison matters
Suppose two identical-looking houseplants grow at different rates, and one sits beside a window. Did the extra light cause the difference? Perhaps—but the plants might also have received different amounts of water, grown in different soil or started at different sizes. Seeing two things occur together does not tell us which one caused the other.
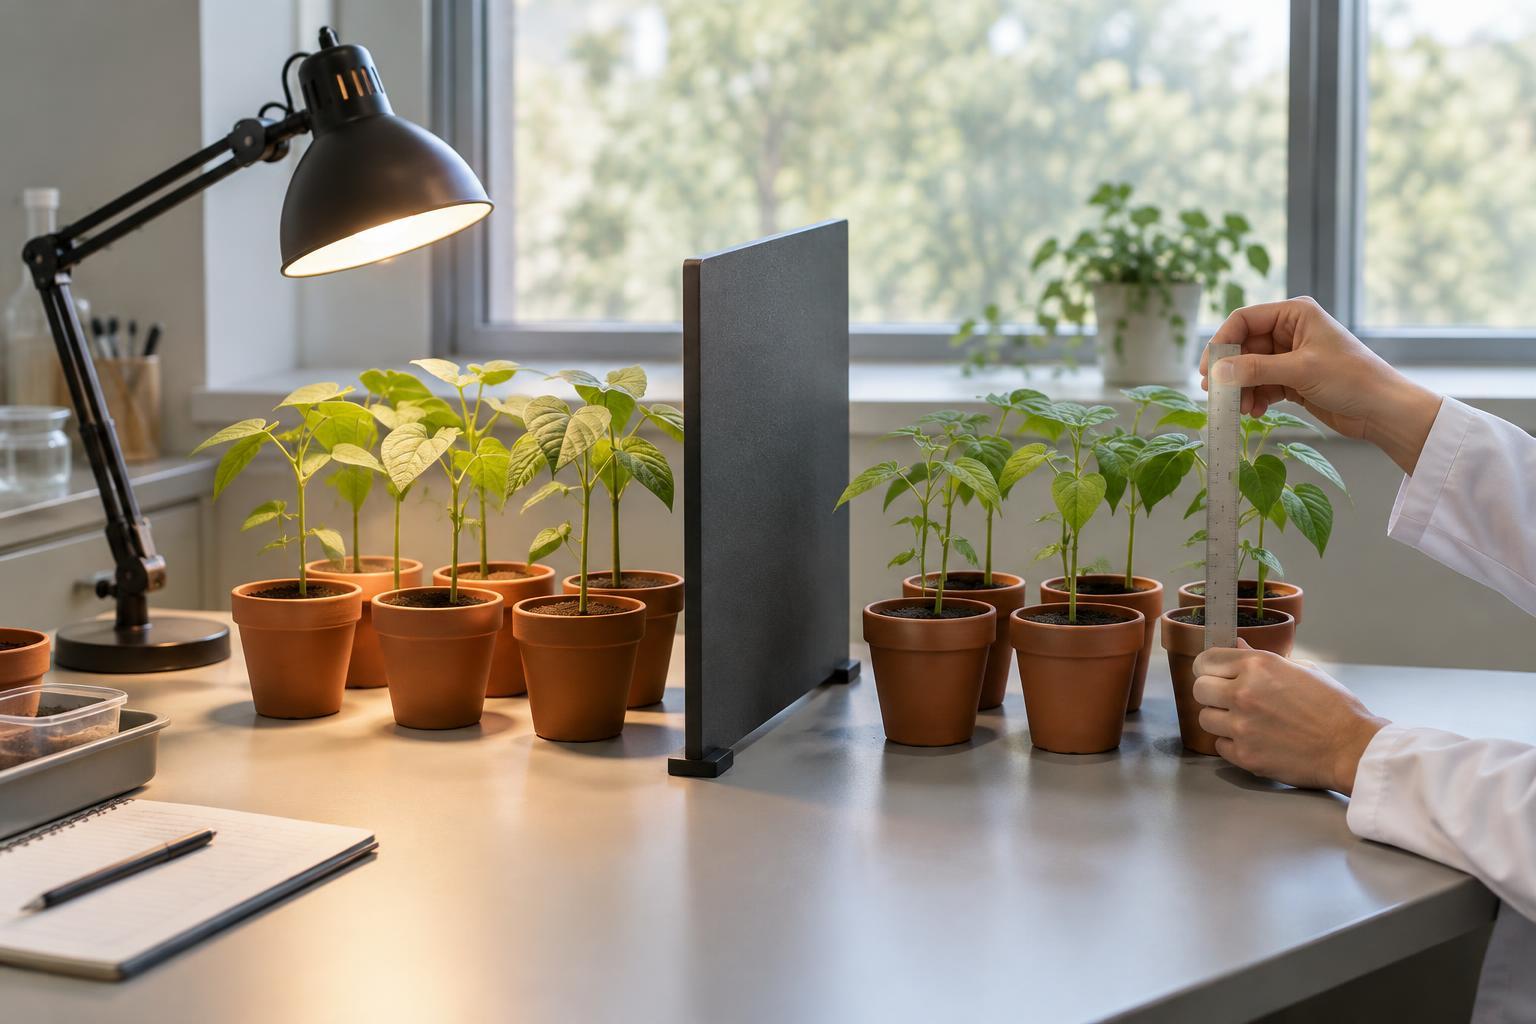
A controlled experiment makes the comparison more informative. Researchers deliberately change a factor they want to test, called the independent variable, and observe an outcome, called the dependent variable. For the plants, the independent variable could be the number of hours under a lamp; the dependent variable could be growth over a set period. The aim is to make other relevant conditions as similar as practical, so that a difference in growth has fewer competing explanations.
What gets changed—and what stays the same
Imagine testing whether extra light affects plant growth. One group receives a chosen amount of light, while a comparison group receives a different amount. Both groups use the same type of pot and soil, follow the same watering schedule and grow in similar temperatures. These shared conditions are controlled variables. They are not the focus of the test, but allowing them to vary freely could make the result hard to interpret.
The comparison group is sometimes called a control group. It does not always mean a group that receives nothing: it might receive the usual amount of light while the other group receives more. What matters is that the groups differ in the factor being tested and are otherwise comparable. A good design also decides in advance how to measure growth—for example, plant height or new leaf count—and measures each group in the same way.
Why repeating and assigning fairly help
Even careful matching cannot make living things identical. Seeds vary, and a small difference in position might change how much light reaches a pot. Testing several plants in each group makes it less likely that one unusual plant will dominate the impression of what happened. Repeating the experiment under similar conditions can show whether the pattern appears again, though repeated results still need thoughtful interpretation.
Random assignment is another useful tool. Rather than putting the largest seedlings in the extra-light group, a researcher can assign seedlings to groups by chance. This helps spread known and unknown differences between groups instead of systematically favoring one. Random assignment does not guarantee perfectly matched groups, especially when groups are small, but it reduces a common source of bias.
Avoiding hidden influences
A factor that differs between groups and could affect the outcome is a confounding variable. If the extra-light plants are also closer to a heater, temperature may help explain any growth difference. A researcher could place lamps where they do not noticeably warm the plants, monitor temperature or arrange the pots so that both groups experience similar warmth. The choice depends on what the experiment is trying to isolate.
Expectations can influence measurements, too. If a person knows which plants received extra light, they might unconsciously measure a borderline leaf differently. Where feasible, labeling pots with codes can keep the person measuring unaware of the group assignments until measurements are complete. This is a form of blinding. It cannot solve every design problem, but it can reduce the influence of expectations when judgments are involved.
What a controlled experiment can—and cannot—show
When groups are comparable and measurements are consistent, a difference in outcomes offers evidence that the changed factor had an effect under the tested conditions. It does not automatically reveal every step of the underlying process. If extra light increases growth, a separate test might be needed to understand which aspects of the light or growing conditions matter most.
Nor can every question be tested by changing just one thing in a perfectly controlled setting. Real-world conditions interact, and some factors are impractical or inappropriate to assign experimentally. Researchers may begin with a simplified test to clarify one relationship, then examine whether it holds across different settings. The central habit is the same: ask what else could explain an observed difference, and design the comparison to rule out as many plausible alternatives as possible.